•
Drizz raises $2.7M in seed funding •
•
Featured on Forbes
•
Drizz raises $2.7M in seed funding •
•
Featured on Forbes


Agentic testing does not replace traditional test automation. It changes where QA spends its time. Instead of writing and maintaining scripts, QA engineers spend more time defining goals, reviewing agent decisions, and governing where autonomous exploration is allowed to go.
This post covers six concrete differences between traditional automation and agentic testing, new skills that matter, how CI/CD pipeline changes, challenges that come with it, and how mature teams combine both approaches rather than picking one.
An agent, in this context, is a software system that takes a high-level goal, reads current state of an application, plans a sequence of actions, executes them, and evaluates outcome. It does this without a human writing out individual steps, its closest cousin in existing practice being AI-driven testing, which agentic testing extends by moving decisions from authoring time to runtime.
The difference from traditional automation is not “AI is added.” The difference is where intelligence sits. In traditional test automation, intelligence sits in the test author, who anticipates every branch and writes each step. In agentic testing, intelligence sits in runtime, which decides what to do based on what it observes. The primitives are not new. Google’s Robo test in Firebase Test Lab has shipped heuristic exploration for years, and Meta’s Sapienz has run search-based exploration across their apps at scale since 2017. What changed is arrival of large language models, which added planning and semantic understanding on top.
The two approaches diverge across every phase of testing lifecycle.
Test creation. Traditional automation is written line by line. Selectors are identified, DOM paths mapped, and wait conditions set. Agentic testing starts from a plain-language goal or a user story. The agent interprets intent and constructs sequence itself.
Execution model. Traditional automation is deterministic. Given same input, it runs same steps against same W3C WebDriver protocol and produces same result. Agentic testing is probabilistic. Given same goal, agent may take a different path on two consecutive runs, depending on app state and its exploration policy.
Maintenance. Traditional automation breaks when UI shifts. A renamed button, a new modal, a moved element ID, and script fails. Agentic testing recognises components by their purpose and adapts. Maintenance load drops, though it does not go to zero.
Failure handling. Traditional automation halts on first unexpected state. An unhandled popup, a network delay, a permissions prompt, and run stops. Agentic testing captures new state, plans a recovery action, and continues.
Coverage shape. Traditional automation covers exactly what a human authored. Agentic testing explores paths a human did not anticipate. Edge cases surface that would never appear in a hand-written test plan.
Human role. Traditional automation makes QA engineer a test author and maintainer. Agentic testing makes same engineer a quality orchestrator: defining goals, reviewing agent decisions, and setting acceptance criteria.
The two are not opposites. They are different points on same spectrum same one that runs from manual testing to automation testing, extended by another leap in where intelligence sits.
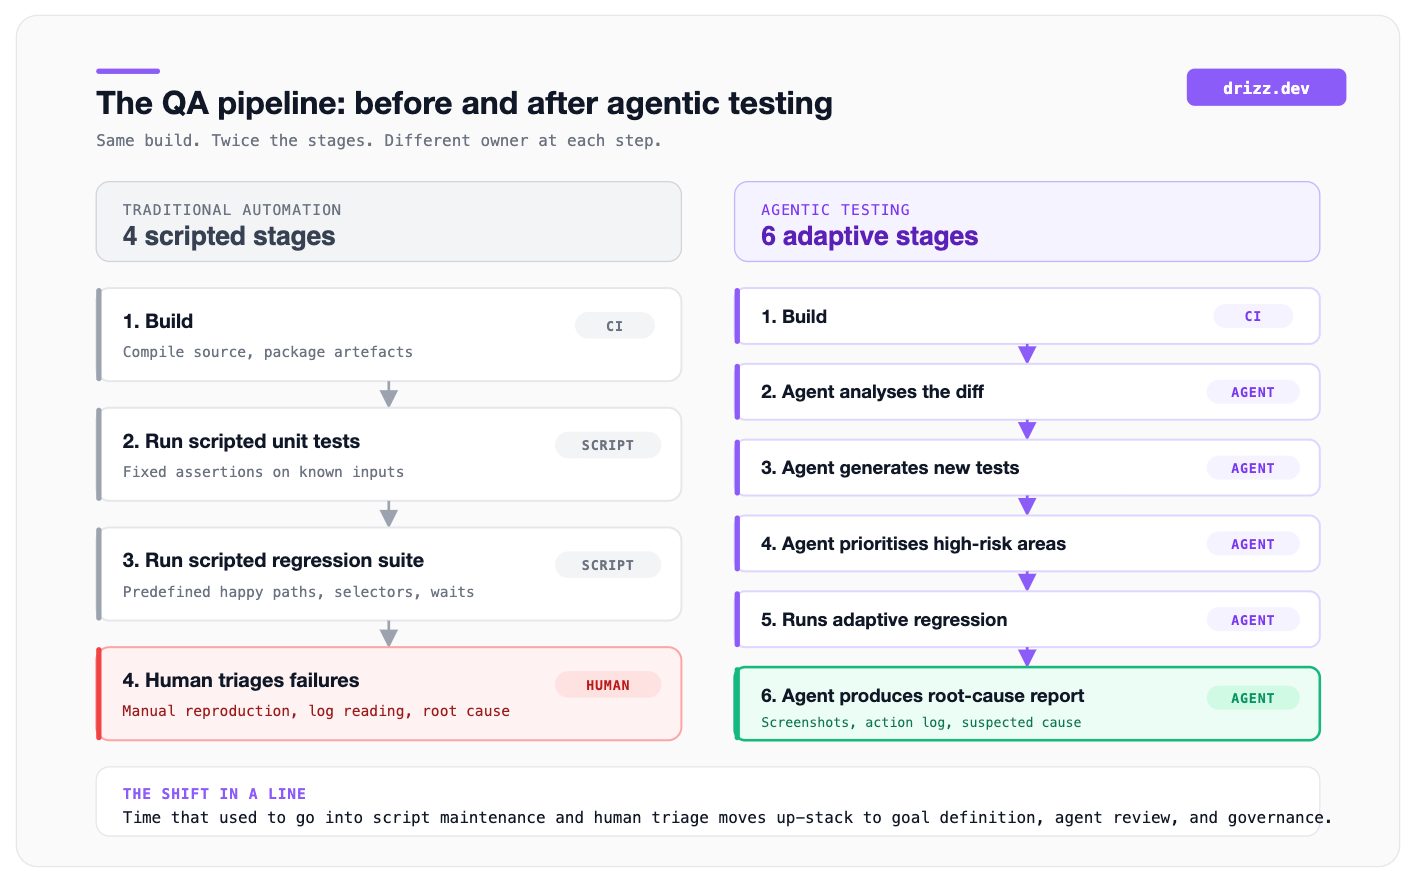
What this diagram helps with: at a glance, it shows why QA time re-allocates when a team moves to agentic testing. Stages that used to be human-authored code become agent-driven decisions, and new stages appear (change analysis, test generation, prioritisation) that had no equivalent in traditional pipeline.
The role does not shrink. It shifts, in same direction that quality engineering has been pulling QA for past several years, and agentic testing accelerates it further.
The traditional test opens with a specific instruction: click Login, enter username, enter password, verify dashboard. The agentic test opens with an outcome: verify that a new customer can create an account and place an order. The agent decides what to click and in what order. The QA engineer writes outcome, not steps.
An agent that reads rendered screen can find a renamed button by using nearby labels or its likely function. Scripted tests would fail on same UI change. This is what vendors mean by self-healing. It is real, but it is not perfect. Some UI refactors still break agent runs, particularly structural redesigns that change multiple attributes at once.
Traditional automation runs scenarios QA has already thought of. Agents run scenarios QA never scripted, including unusual input sequences, unexpected navigation orders, and edge-case permutations. This is where crashes hide and where a scripted test suite, by definition cannot reach.
Agents can read a user story, a requirement, or an API specification and generate a test suite that covers it. For a password requirement of “must contain at least one number,” an agent will produce cases for valid input, no number, unicode characters, maximum length, empty input, SQL injection attempts, and emoji input. A human test author writes maybe three of those on a good day.
QA time re-allocates. Less on Selenium maintenance and locator repair. More on defining risk areas, setting acceptance criteria, reviewing what agent chose to do, and validating that agent’s decisions actually reflect business intent.
Traditional automation rewards Selenium, Playwright, Cypress, XPath, and CSS selectors. Agentic testing adds a different toolkit:
Programming does not stop mattering. Agents produce code that still needs review, extension, and integration.
An agentic testing platform introduces failure modes that traditional automation does not have. Someone in QA function ends up owning them.
This is a genuine expansion of QA remit. Testing tester is now part of job.
The pipeline itself grows new stages. A traditional pipeline runs four steps: build, run unit tests, run regression suite, report failures. An agentic pipeline runs six: build, agent analyzes changes, agent generates new tests for those changes, agent prioritizes highest-risk areas, agent runs adaptive regression, and agent produces a summarized root-cause report on failures.
The added stages replace human triage. That is where wall-clock savings come from. It is also where trust question becomes real: teams need enough confidence in agent’s summarization to skip manual triage pass, and building that confidence takes weeks to months of observed runs.
Agentic testing has real limitations that teams need to plan for.
Most mature QA organizations do not pick one approach. They combine both.
Traditional automation stays anchored on stable, low-risk, deterministic paths: unit tests, API validations, and critical business flows where repeatability is essential. These are cheap to run, fast, and predictable.
Agentic testing gets deployed at dynamic decision points: variable user flows, complex UI layouts, exploratory coverage, root-cause analysis on failures, and adaptive regression on rapidly changing screens.
The two layers reinforce each other. Traditional automation catches regressions on scripted happy paths. Agentic testing catches failures that live off happy path.
Three platforms represent a useful cross-section of market: one AI-native mobile agent, one AI-native cross-platform agent, and one enterprise autonomous suite. Between them they cover a range of teams shipping agentic testing in production today.
Drizz is a vision-based mobile testing agent that reads rendered screen way a human does, plans flows in plain English, and executes them on real iOS and Android devices without a scripted step. There are no XPath selectors, no accessibility identifiers, and no per-platform locator files. The same natural-language flow runs identically on both platforms and survives most UI refactors that break Appium.
Reported flakiness on production customer suites sits around 5%, against an 8-15% industry baseline on selector-based codeless tools. Every run returns per-step screenshots, action logs, and an AI-generated explanation of any failure, so a QA reviewer can attribute a break to a real bug or a genuine regression without replaying run. Drizz is closest thing to a full-loop agentic operation available for mobile today: Read goal, observe screen, plan next action, execute, verify, log, and repeat.
Suited to QA teams at 200-5,000-person shops shipping weekly on native or React Native applications, particularly in fintech, delivery, and health verticals where UI moves constantly and script maintenance has become dominant cost.
Momentic runs an LLM-planned agent across web and mobile. Their V3 agent plans whole flow up front, caches resolved steps, and self-heals on failure rather than crashing. On mobile side, agent is web first in maturity, but roadmap is closing gap. Momentic is most direct AI-native competitor to Drizz on planning fidelity, and their public documentation is more detailed than most of market on how agent’s decisions are made.
Best fit for teams that already run web autonomous tests and want to consolidate mobile onto same platform, or for teams evaluating a second AI-native option alongside Drizz for a comparative pilot.
Functionize is an enterprise-grade autonomous test platform that emphasizes full test lifecycle automation: generating tests from requirements, executing them, maintaining them as app changes, and providing analytics on what changed and why. Historically web-focused, with growing mobile coverage. Widely deployed at Fortune 500 QA functions and reviewed as one of strongest platforms for teams looking to retire large legacy Selenium suites without rewriting every test by hand.
Best fit for enterprise QA organizations that need governance, audit trails, and integration with existing test management systems and that have a budget for annual enterprise contracts rather than usage based pricing.
Agentic testing is not free coverage. Inference costs scale with run count. Non-deterministic paths make cross-run comparisons harder. Reasoning failures produce false positives and false negatives that would not exist in a scripted suite. Governance and audit trails become QA’s responsibility in a way they were not before.
And no agent yet reliably tests flows that require external state changes arriving through a socket, another user’s action, or a delayed backend event. Those cases still need scripted tests and probably will for a while.
Is agentic testing same as AI-assisted testing?
Not quite. AI-assisted testing uses a model to help a human write or maintain a test. The test then runs deterministically. Agentic testing uses an agent at runtime: agent decides what to do based on what it sees, and running itself is test.
Will agentic testing eliminate QA role?
No. The role shifts. QA engineers move from writing and maintaining scripts to defining goals, reviewing agent decisions, setting acceptance criteria, and governing what agents can and cannot do. The volume of work does not go down; character of it changes.
How reliable are agent decisions today?
Reliable enough for exploratory coverage, regression sweeps, and change-triggered test generation. Not yet reliable enough for compliance evidence that requires exact steps in exact order without human review. Serious platforms combine agent runs with scripted checks on critical paths.
How does agentic testing fit into an existing CI/CD pipeline?
Alongside, not instead. Scripted regression continues to run on every commit. Agentic exploration runs on a schedule (nightly or per release) because inference cost per run is higher than a scripted test. Failure reports from both layers converge into same triage view.
What’s biggest mistake teams make when adopting agentic testing?
Deploying it as a full replacement for scripted tests before it has proven itself on their specific app. The right pattern is to run agentic testing alongside scripted testing for two or three release cycles, measure how often each layer catches something others missed, and only then decide how much of scripted suite is safe to retire.




©Drizz 2026 • All Rights Reserved






